 Get hyper3-clip-v1
PaperECCV BEW 2026
Hyper3-CLIP: hierarchy-conditioned hyperbolic vision-language training
Query-conditioned visual pooling and hierarchical training in hyperbolic space.
hyper3-clip-v1 is our hyperbolic image–text model for visual search. Search from broad categories to specific descriptions, matching objects, attributes, and relationships.
Explore saved comparisons of hyper3-clip-v1 and OpenAI CLIP on product, fashion, and object search.
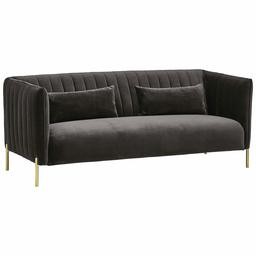
“a product photo of grey velvet sofa”
a product photo of grey velvet sofa: Frederick Mid-Century Modern Tufted Velvet Sofa Couch 77.5 W Grey, with metal, brass finish, wood, velvet upholstery, tufted
Exact product
Frederick Velvet Sofa
#1Frederick Velvet Sofa
Exact product #2
Uptown Velvet Daybed
 #3
Frederick Velvet Sofa
 #4
Frederick Velvet Sofa
 #5
Uptown Velvet Daybed
 #1
Uptown Velvet Daybed
#2Uptown Velvet Daybed
 #3
Uptown Velvet Daybed
 #4
Alonzo Leather Sofa
#5Frederick Velvet Sofa
Exact productSee how your own catalog compares.
Get a 48-hour evaluationFrom matching the details in a description to finding products and objects. Explore the compositional benchmark and our visual-retrieval evaluations below.
SugarCrepe · macro accuracy ↑
| Model | Accuracy ↑ |
|---|---|
| hyper3-clip-v1 | 79.54% |
| Jina CLIP v1 | 78.20% |
| Jina CLIP v2 | 75.02% |
| OpenAI CLIP ViT-B/16 | 73.06% |
Image and product retrieval against OpenAI CLIP.
Swipe to compare →
| Industry / Dataset | Benchmark | hyper3-clip-v1 | OpenAI CLIP | Readout |
|---|---|---|---|---|
| Ecommerce Catalog Retrieval – Amazon Berkeley Objects | ||||
| Retail catalogs500 product images, 20 product types | Product-type mAP | 0.582 | 0.552 | +3.05 pts |
| Retail catalogs50 parsed catalog departments | Department mAP | 0.264 | 0.212 | +5.20 pts |
| Retail catalogsParent category retrieves diverse children | Child coverage@50 | 0.780 | 0.655 | +12.50 pts |
| Fashion Matching & Search – DeepFashion In-Shop | ||||
| Apparel retail710 photo queries, 741 catalog photos | mAP | 0.635 | 0.352 | +28.3 pts |
| Apparel retailSame product across views; query photo excluded | Recall@1 | 0.759 | 0.456 | +30.3 pts |
| Apparel retail180 text queries, separate 1,120-photo pool | Hit@10 | 0.572 | 0.550 | +2.2 pts |
| General Visual Hierarchy – COCO Objects | ||||
| Object search5,000 COCO val images, 80 categories | Category mAP | 0.554 | 0.532 | +2.22 pts |
| Object search12 object supercategories | Supercategory mAP | 0.536 | 0.516 | +2.08 pts |
| Object searchCoverage of child types under broad labels | Child coverage@100 | 0.887 | 0.951 | CLIP +6.40 pts |
hyper3-clip-v1 brings images and text into a shared hyperbolic space for broad-to-specific retrieval and compositional matching.
HyperView is an agent-native workbench for inspecting embedding spaces, curating datasets, and understanding why retrieval results fail.
Send a small sample of your images and queries. We run hyper3-clip against your current baseline and return a short report within 48 hours: metrics, ranked examples, and whether a pilot is worth it. No discovery call required.
PaperECCV BEW 2026
Query-conditioned visual pooling and hierarchical training in hyperbolic space.

ArticleQdrant
Searching hierarchical embeddings with Qdrant.
BlogJun 11, 2026
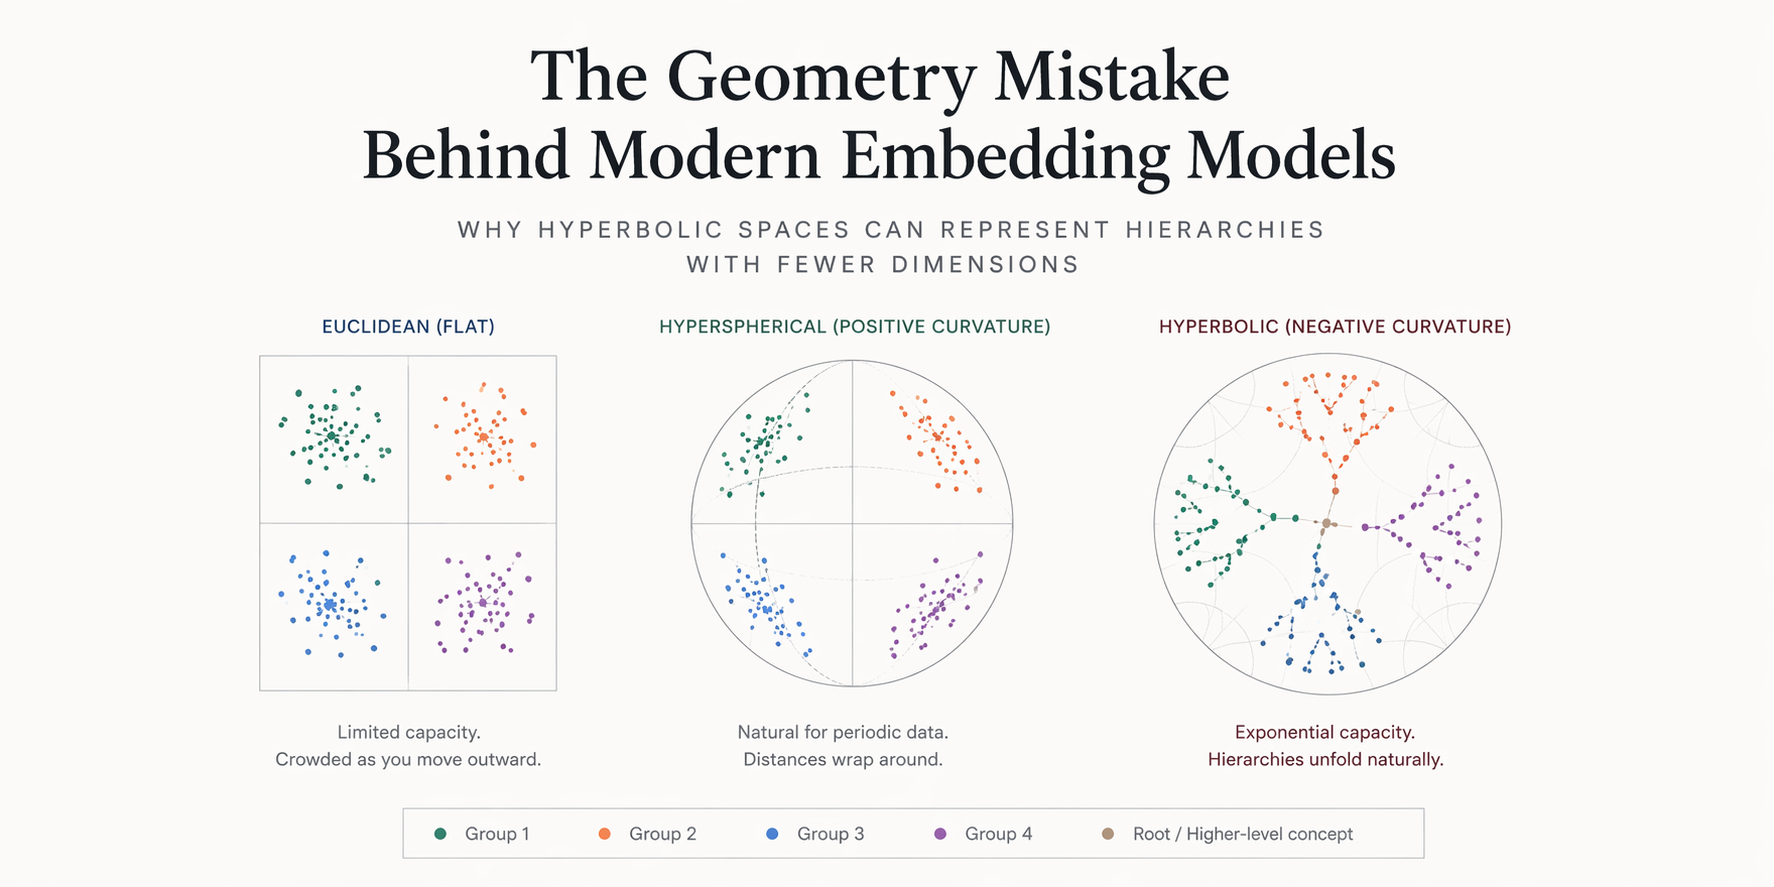
Why mainstream ML's reliance on Euclidean manifolds is a mistake, and how hyperbolic spaces can efficiently encode hierarchical data with fewer dimensions.
